Testing Without a QA Team: What to Test First (and How Not to Drown in Flaky Tests)
A practical guide for freelancers and small teams: how to decide what to test, how to split unit, integration and e2e, and what to automate before every deploy becomes an act of faith.
On a recent project — a booking SaaS for clinics — we were two people: me and a client who answered support tickets between patients. No QA, obviously. Every Friday, a deploy. Every Friday, the same scene: deploy shipped, both of us staring at Slack like it was an interrogation.
The strange part is that we weren’t testing “too little”. The problem was different. We didn’t know what to test first, with what, or when to stop. Testing everything is impossible when you’re one person; testing nothing gets expensive fast when your system handles money and schedules. This post is the map I wish I’d had that week.
1. The right question: where would the bug hurt you?
The first testing decision isn’t technical, it’s a priority call. You don’t test what’s easy to test; you test what hurts when it’s broken. Before writing a single test, run your system through this filter:
- Is it money? Calculations, totals, discounts, invoicing.
- Is it data you can’t recover? Bookings, signups, deletions.
- Has it broken before? Code with a bug history is a strong candidate.
- Would the user hit it in the first 30 seconds?
- Would it page someone you can’t call at 3 a.m.?
For the booking SaaS, the answer was uncomfortable: neither login nor styling was the real risk. It was overlapping appointments. A single module concentrated nearly all the business risk. That’s where we started — not because it was fun to test, but because it was the only place a bug cost us customers.
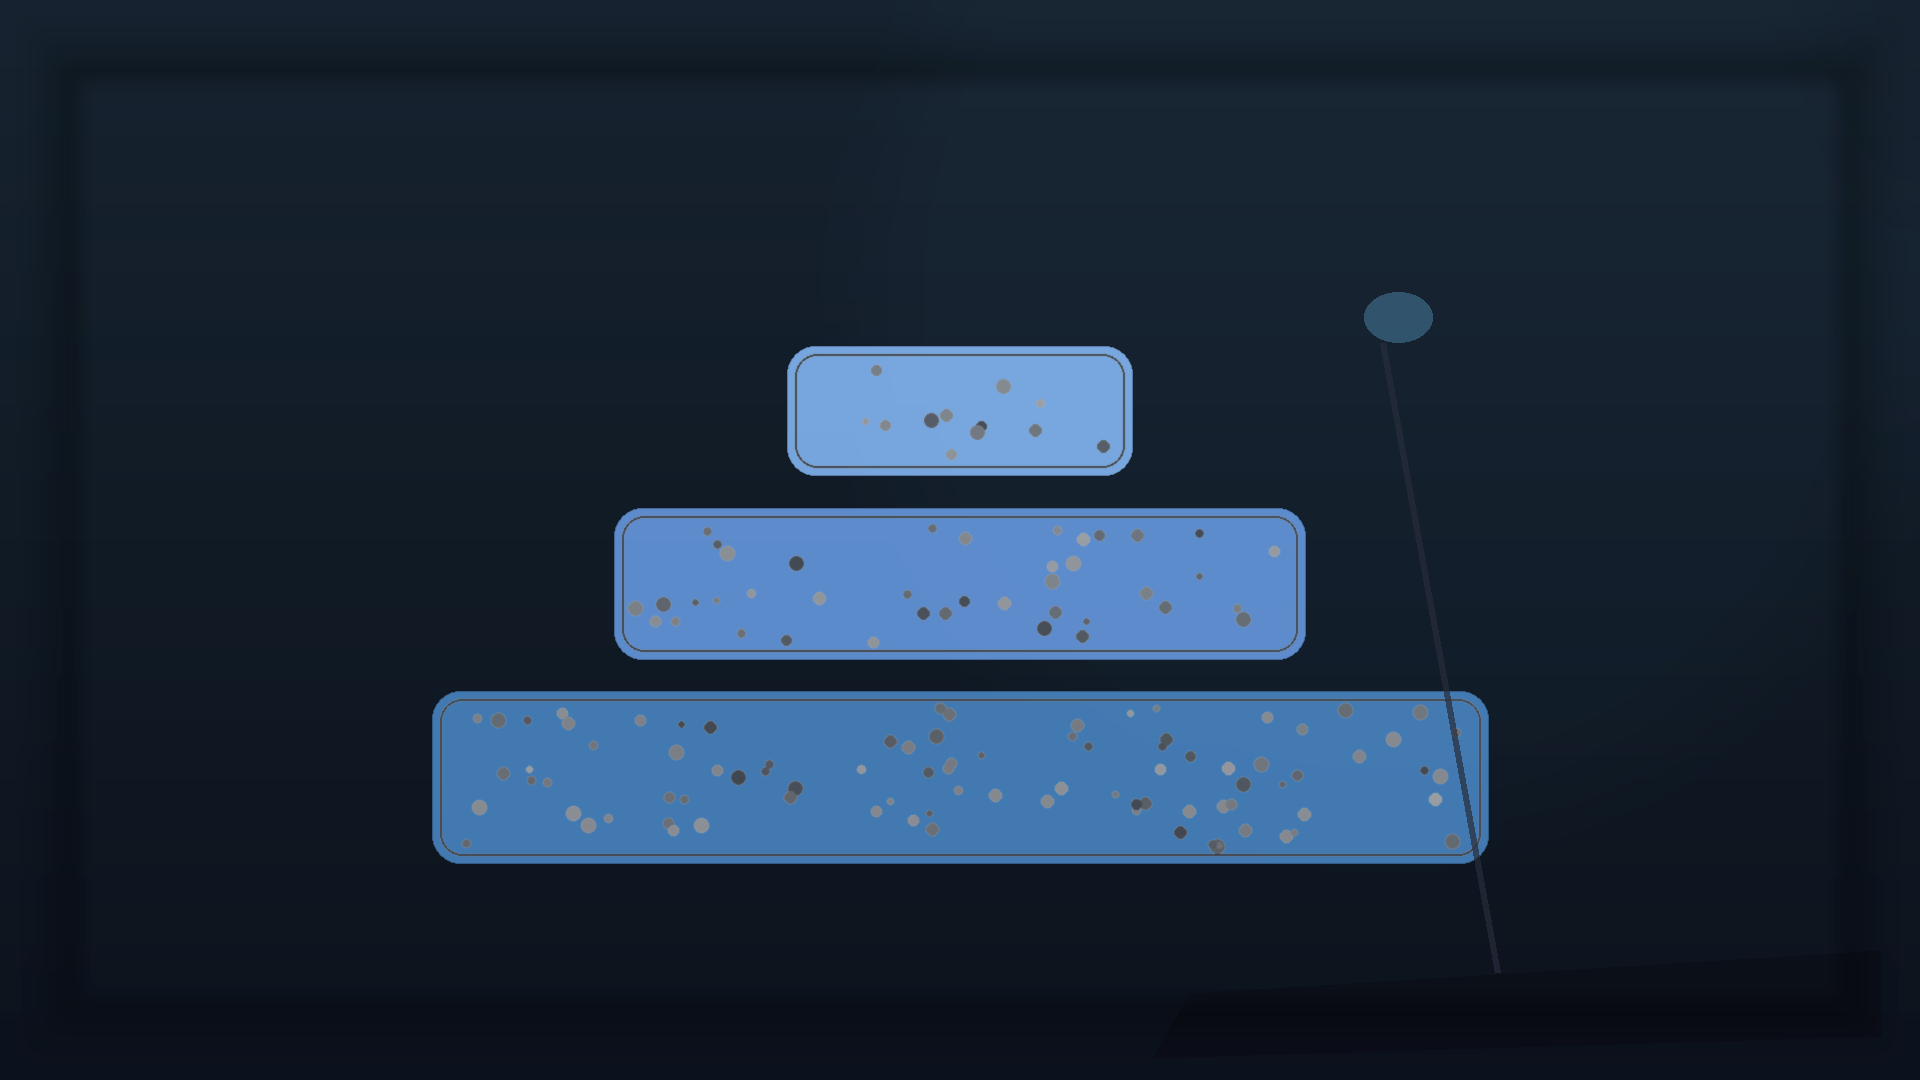
2. The pyramid, translated into budget
The testing pyramid (unit / integration / e2e) is usually presented as aesthetic dogma. For a small team it’s something more useful: it’s a budget. Each layer buys a different kind of confidence at a different price.
- Unit tests are one-dollar bills: cheap, fast, you can afford hundreds. They buy precision: the business rule is exactly right.
- Integration tests are fifties: fewer of them, pricier. They buy reality: the pieces actually fit together (database, HTTP, emails).
- E2E are thousand-dollar bills: rare, slow, fragile. They buy the big picture: the user’s full flow walks end to end.
The classic small-team mistake is spending the entire budget on the expensive layer. Look at the difference:
// ❌ Launching a browser to verify a business rule
test("total with discount", async () => {
  await page.goto("/checkout?subtotal=100&discount=20");
  expect(await page.textContent("#total")).toBe("80");
});
// ✅ The same rule, no browser, milliseconds
test("applies a 20% discount to the subtotal", () => {
expect(calculateTotal({ subtotal: 100, discount: 0.2 })).toBe(80);
});The first test can break because of CSS, timing, or a copy change. The second only fails when the business rule is wrong. That’s precisely the question you want answered.
Where the pyramid earns its width is at the boundaries: endpoints, repositories, queues. There, an integration test with controlled data is gold:
test("refuses to book two appointments at the same time", async () => {
  const repo = inMemoryRepo([{ date: "2026-10-05 09:00" }]);
  const res = await createAppointment({ date: "2026-10-05 09:00" }, repo);
  expect(res.status).toBe(409);
});
3. What to automate first
With the budget clear, here’s the order I’d follow on a small team:
- Pure business rules → unit. Calculations, validations, transformations. They come by the dozen and cost little.
- Boundaries and endpoints → integration. Routes, queries, database interactions with controlled test data.
- 5 to 10 critical flows → e2e. No more. Signup, payment, the flow that generates revenue. If your e2e suite has 60 tests, it isn’t a suite — it’s a liability.
- Every production bug → a test that reproduces it before you fix it. Best ROI in testing: you turn incidents into permanent guards in the suite.
And the list of what not to automate matters just as much:
- Trivial getters and setters.
- Pure visual styling (that’s what review is for).
- Basic validations the framework already gives you.
- Anything where testing costs more than fixing the bug.
On the booking project, we started with a single afternoon: the overlaps(appointment, existing) function and four tests. Not heroic. But the next time we touched that module, deploying stopped being a bet and became a verification.
4. Flaky tests: how to keep from drowning
A flaky test (fails, you rerun, it passes) is worse than a broken one. The broken test points at a problem; the flaky one teaches everyone to ignore the alarm. It’s the boy who cried wolf, repository edition.
Cause number one of flakiness is waiting on the clock instead of waiting on the state:
// ❌ "I wait and pray"
await new Promise((r) => setTimeout(r, 3000));
expect(await page.textContent("#status")).toContain("Done");
// ✅ Wait for the condition, not for luck
await expect(page.getByText("Done")).toBeVisible({ timeout: 5_000 });After that fix, my house rules are few and firm:
- One retry is a seatbelt; two retries are a hiding place. Runner retries exist to absorb network noise, not intermittent bugs.
- Quarantine, not cohabitation. Flaky test: flag it, write it down, fix or delete it within days. It should never live as a false green in the suite.
- Every test owns its data. Deterministic seed, no relying on whatever the previous test left behind.
- Flaky gets fixed or removed. There is no “we’ll leave it as is”.
5. Common mistakes (I’ve seen them all)
- Testing out of guilt. Chasing a coverage percentage as a goal fills your suite with useless tests you must maintain.
- Happy path only. No boundaries: bugs live in discounts, dates, duplicates, and empty fields.
- Tests that depend on order. If order matters, it’s a badly written integration test — and a fragile one.
- Sleeping instead of waiting. A stock
setTimeoutmanufactures flakiness at industrial speed. - The “temporary” red suite. Three weeks red and the whole team learns to ignore CI.
- Automating the demo instead of the invoicing. What photographs well in a video isn’t what breaks your Tuesday.
The short version
The goal was never “being tested”. The goal is that on Friday at 5:04 p.m., when you deploy, you know exactly what your suite is telling you: if it’s green, the flows that pay the bills walk. A small team with that clarity tests better than a floor full of people extinguishing fires without a map.
Which flow in your system is still an act of faith every time you deploy? That’s your first test. And if you’d like a second pair of eyes to shape the pyramid for your project, you know where to find me.